The problem
ISCVAM’s users—principal investigators and wet-lab researchers—had deep biological expertise but no direct computational path to analyze their data. Finished experiments sat in an analyst queue, creating a bottleneck between data generation and biological interpretation.
The automated pipelines eliminated this bottleneck. Ingestion, quality control, data processing and annotation now execute without manual analyst intervention across all 198 studies, transforming data delivery from a multi-week scheduling delay into a predictable runtime.
Scope
Mine
The data layer — two processing R pipelines, QC, dimension reduction, clustering & annotation, parameterization and scheduling, HPC orchestration and run monitoring, and the output schema.
Not mine
The platform — the application design, the visualization and clustering interfaces, and cross-dataset comparison. Built by the software engineering team: the React frontend and Node backend in the lab repository.
Pipeline architecture
Two pipelines, one for scRNA-seq and one for sc-multiome.
- 01Ingest
- 02Processing & QC
- 03Annotation
- 04Dimension reduction & clustering
- 05Export
For technical details, see the lab repository.
- Input — 10x Genomics output from the sequencing core (10x Genomics scRNA-seq matrices or Paired multi-modal feature matrices — transcriptomic and epigenetic streams from the same cells).
- Output — one ISCVAM-compliant H5 file per study on a fixed schema
Orchestration at scale
The pipelines run as Slurm batch job arrays, one task per study, with R-level parallelism inside each task.
The constraint
Studies with the largest sample sizes (over ~100k cells) require single-node isolation, multi-gigabyte memory allocations and multi-hour runtimes. Submitted in arbitrary order, they congest the queue and push every smaller studies behind them into a sequential wait.
The decision
Arrays are ordered by data size, smallest first. Lightweight studies clear quickly and release their allocations, so heavy studies land on dedicated nodes without starving the rest of the batch.
The ordering has a second benefit: a systematic problem surfaces in the first few fast-running tasks rather than after the resource-intensive studies have already burned hours.
Failure isolation
The array structure contains failure to a single task — a study that fails takes down its own task and nothing else, and I resubmit just that one. Isolating high-memory studies to single nodes kept out-of-memory crashes from cascading through the rest of the batch.
Checkpointing
Each stage of the pipeline exports its intermediate R objects on completion. If a study fails downstream, execution resumes from the last valid checkpoint rather than re-running compute-intensive upstream processing.
- Fault tolerance and cost
- Avoids re-spending CPU hours on upstream steps like annotation and multi-resolution clustering, turning a failure into a quick, localized retry.
- Auditability
- Intermediate objects stay on disk, so the step-by-step path from raw ingestion to final output remains reproducible and inspectable.
- Trade-off: storage overhead
- Retaining intermediate R objects for 198 studies is a significant claim on HPC disk storage across runs.
Run monitoring
Slurm writes stdout and stderr per array task by default, which at 198 studies is 198 files to open rather than a way to see the run. I built a layer over it: a master file tracking submission and status across all studies, and a second capturing wall time and memory, both by parsing the Slurm outputs into one view.
Failure mode: defaults don't scale
Failures were driven primarily by default parameter limits and resource constraints, and the pattern only manifested beyond small datasets. Standard default settings worked smoothly on smaller studies, but medium and large cohorts would hang or exceed Slurm wall-time limits. Initially, this masked itself as an infrastructure bottleneck rather than a parameterization issue.
Once it was clear that standard defaults are optimized for typical small sample size runs and not for the largest studies in a set, I implemented dynamic, size-aware parameter tuning. The broader engineering lesson: validating a pipeline on small test samples offers no guarantee of production scalability, so I now evaluate pipeline stability as a function of data scale.
What the platform does
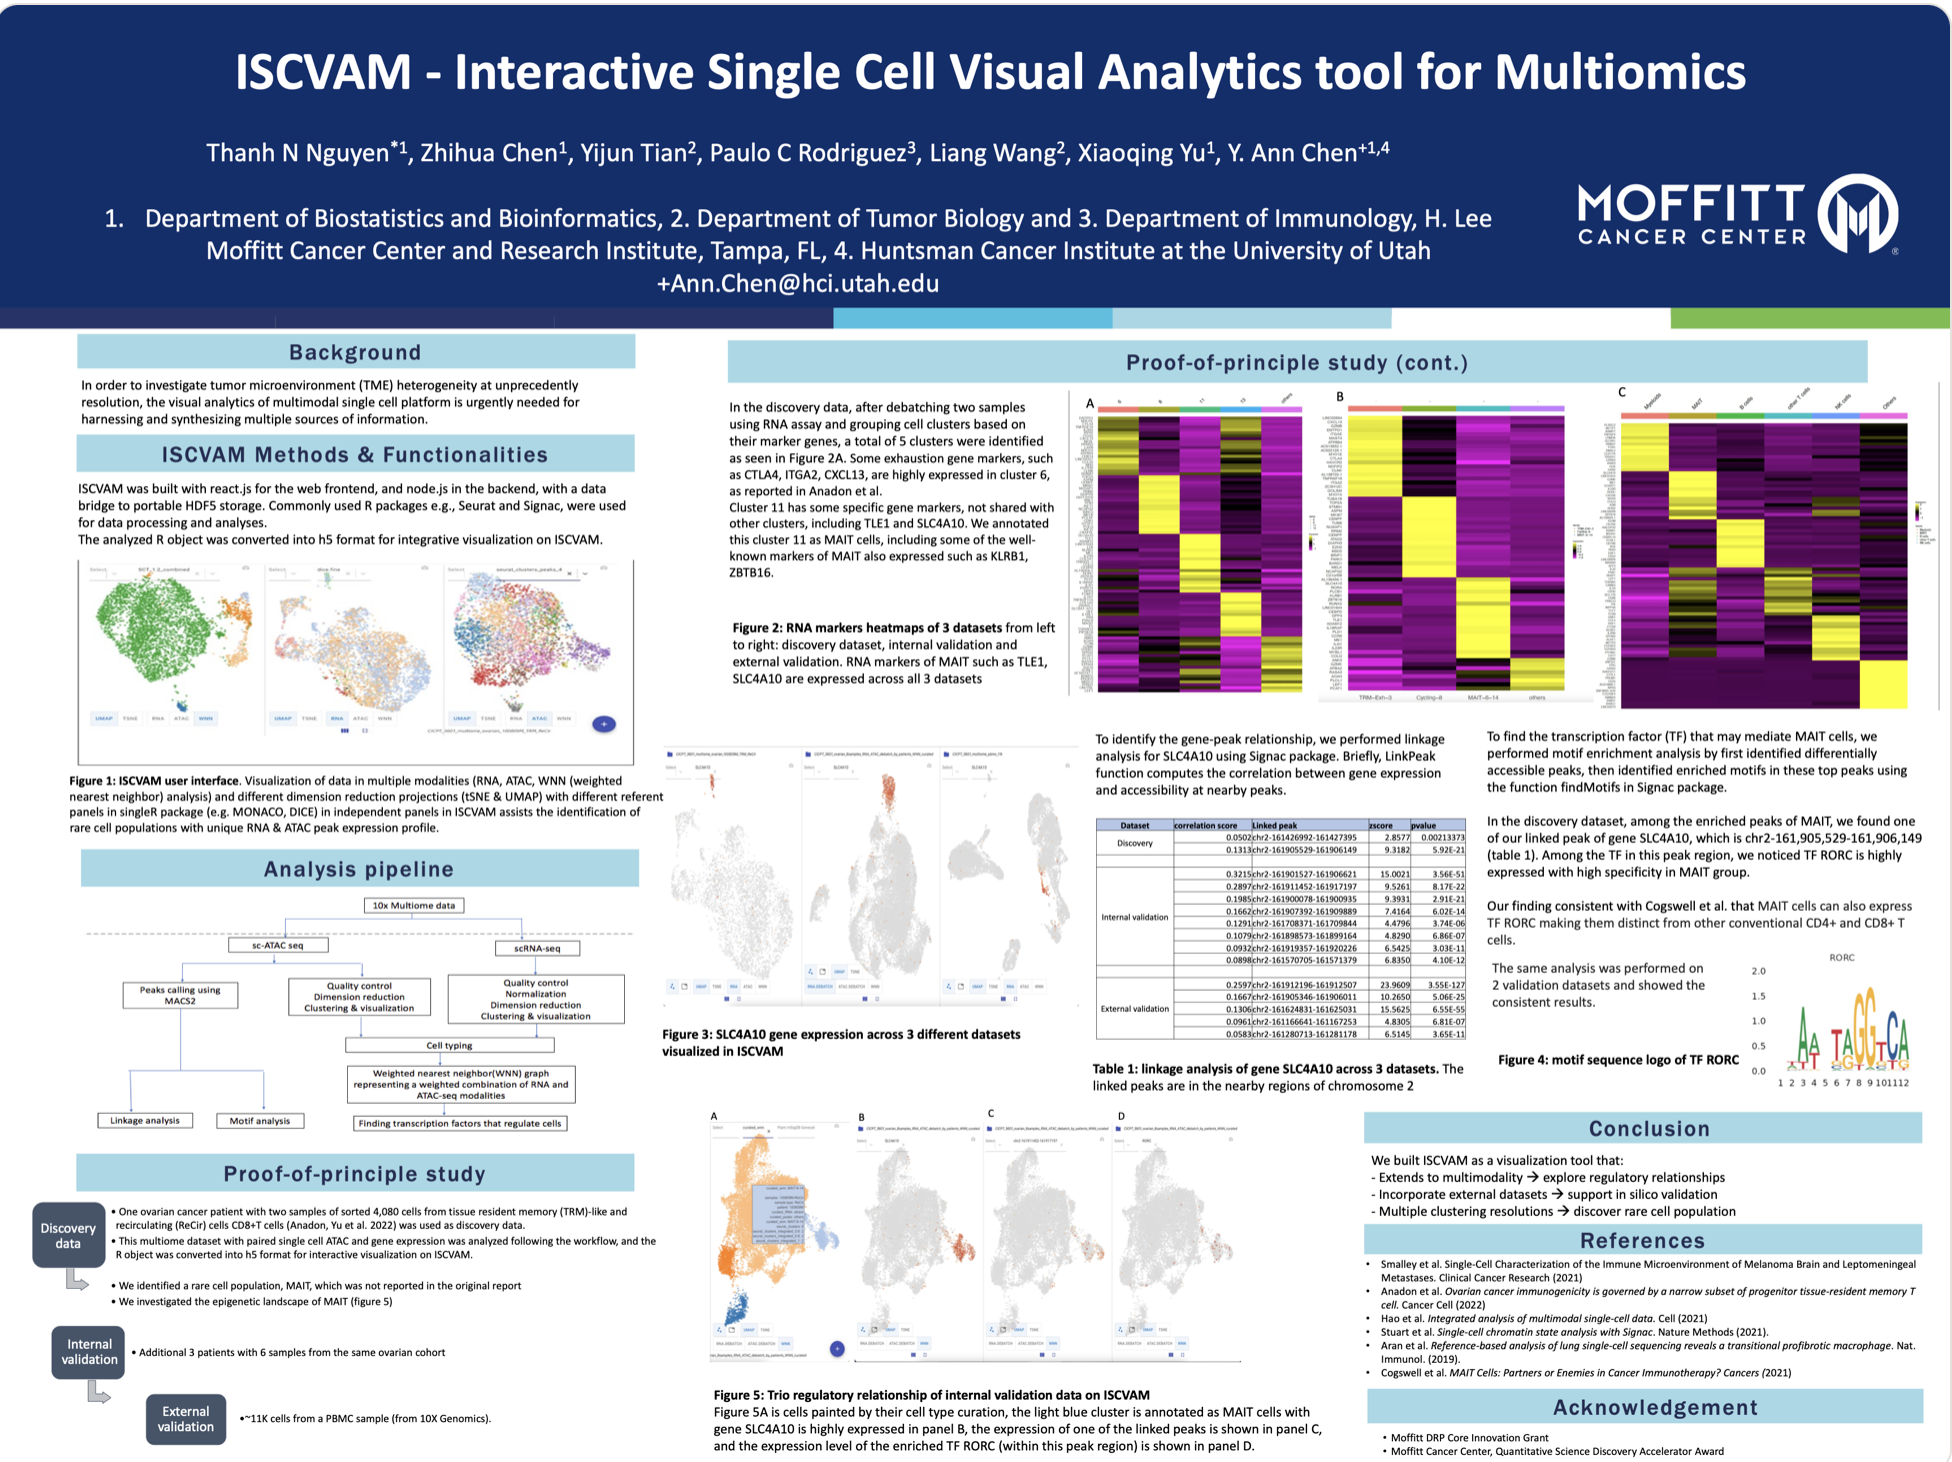
ISCVAM is an interactive visual analytics platform for high-dimensional oncology data, integrating sc-RNA and sc-ATAC so transcriptomic and epigenetic profiles can be studied in the same cells. Flexible clustering surfaces rare cell populations, and cross-dataset comparison across up to three datasets supports reproducibility checks. Accepted for presentation at AACR 2023.
My contribution is the layer beneath it: the data orchestration and the HDF5 data contract the application reads from.
Tech Stack
- PipelinesR · Seurat · Signac
- OrchestrationSlurm job arrays · Batch execution
- EnvironmentDocker
- OutputHDF5